
 Santiago Fernández de Valderrama Aparicio
chore(funding): route funding to the project's Open Collective and verify the repo for FLOSS/fund (#4653)
2周前
feat(latex-tex): support resumeItemWithoutTitle bullets and resumeSubItem skills (#2120)
3个月前
fix(cli-flags): reject empty value in --flag= form when requireOperand is set (#5127) (#5255)
3小时前
fix(plugins): pass the data root to plugins through ctx, so gmail and apify write under it (#5139)
6小时前
chore(coderabbit): incremental reviews, recipes and post-merge drift reports (#3772)
上个月
fix(repo): add .gitattributes so Windows checkouts stop producing whole-file diffs
2个月前
feat(latex): opt-in local LaTeX engine installer so the latex path compiles out of the box (#5133)
9小时前
Merge origin/main into feat/external-data-dir: take-both resolution + drift routing
2个月前
fix(agent-inbox): number resolve against file position, not the pending view (#2739)
上周
fix(tracker): resolve status aliases through states.yml in analyze-patterns and tracker-sync-check (#5065)
前天
docs: fix stale ARCHITECTURE block/script counts; name the scanner's web-search queries (#4907)
4天前
feat(set-status): archive the JD automatically on the transition into Interview (#4524)
上周
Merge origin/main into feat/external-data-dir: take-both resolution + drift routing
2个月前
feat(cv): ats-payload.mjs — an ATS payload transform (one safe fold, three lints) (#3422)
上周
fix(batch): merge into the locked pipeline.md instead of overwriting it with the start-of-run snapshot (#4912)
5天前
fix(paths): resolve user-layer files via the data root in batch-tailor, cv-templates and openrouter-runner (#4570)
2周前
fix(extract): read the content root with the most rendered text, not the first (#4905)
前天
fix(pdf): read a local candidate.photo path only when config/profile.yml names it (#5094) (#5143)
15小时前
上个月
community: add Code of Conduct, Security, Support, Governance + improve issue templates
6个月前
fix(providers): a lone surrogate in one id/slug no longer aborts the whole page
上个月
feat(contacto): surface saved internal-referral contacts before cold search (#4692)
2周前
feat(test-all): run the inline sections alongside the discovered suites (#5146) (#5150)
6小时前
docs(contributing): scope the issue-first steps to the cases that need one (#5025)
3天前
feat(coverage-check): explain why the scanners missed a posting found by hand (#4849)
4天前
feat(pdf): guard CV work experience against non-chronological order (#4489)
2周前
feat(templates): let a template pack declare the sections it owns (#3852) (#3916)
5天前
feat(scan): SmartRecruiters requisition ids and opt-in language-aware dedup (#4613)
上周
feat: dockerize project for hosts blocked from native Playwright install (#625)
4个月前
fix(fetch-jd): read JDs from company-careers gh_jid links and SmartRecruiters (#4673)
2周前
fix(fingerprint): non-Latin employers no longer collapse to the same company key (#2501)
2个月前
feat(tracker): fix-report-links.mjs repairs rows whose report link is dead (#4750) (#4751)
上周
fix(portals): read the data root's portals.yml in fix-slugs and validate-portals (#4287)
3周前
feat(cv-facts): flag scope-verb inflation and unsourced adoption claims (#3784)
5天前
feat(latex): opt-in local LaTeX engine installer so the latex path compiles out of the box (#5133)
9小时前
fix(liveness): keep npm packages out of what the web loads from liveness-browser (#5251)
7小时前
refactor(lib): one shared walkTree() so the nested-checkout gate is a ban, not a dataflow judgement (#3818) (#3908)
前天
feat(latex): opt-in local LaTeX engine installer so the latex path compiles out of the box (#5133)
9小时前
feat(set-status): archive the JD automatically on the transition into Interview (#4524)
上周
fix(keyword-match): read the ## Extracted Keywords heading batch workers write (#4851)
上周
fix(tracker): resolve tracker paths via resolveTrackerPath(DATA_ROOT) across CLI tools (#4087) (#4088)
2周前
fix(liveness): keep npm packages out of what the web loads from liveness-browser (#5251)
7小时前
refactor(tracker): share failUsage between set-status and mark-pdf-ready (#5238)
10小时前
fix(story-bank): stories an evaluation adds aren't invisible to npm run star anymore (#4684)
5天前
fix(sync-pdf-flags): set the PDF flag only while the CV PDF is on disk (#4777) (#4565)
4天前
Merge origin/main into feat/external-data-dir: take-both resolution + drift routing
2个月前
feat(doctor): CLI-aware Playwright MCP detection + OpenCode config support (#2247)
3个月前
fix(data-root): keep the code root and the data root apart in openrouter-runner and batch-runner (#5116)
昨天
fix(paste-reply): serialize concurrent appends so no reply candidate is dropped (#4922)
4天前
docs(path-resolver): name path-resolver.mjs as the module scripts use to resolve the data root and tracker path (#4809)
4天前
fix(pipeline-lock): make OWNERLESS_GRACE_MS env-overridable, fixing flaky test 16 (#4557)
2周前
refactor(lib): one shared walkTree() so the nested-checkout gate is a ban, not a dataflow judgement (#3818) (#3908)
前天
chore: resolve user-layer paths from getCareerOpsRoot() in read/analysis scripts
3个月前
feat(validate-profile): config/profile.yml is never validated, so a misspelled key silently does nothing (#3981) (#3982)
3周前
ci(release): open release PRs with a GitHub App token; keep career-ops Latest after any release (#4462)
3周前
fix(reply-watch): bind legacy review consent to unchanged tracker identities (#5034)
11小时前
fix(reserve-report-num): reject unrecognized arguments instead of reserving a number (#4914)
4天前
fix(scan-ats-full): refuse --resume when a portals.yml filter changed since the checkpoint (#5084)
前天
fix(scan-hn): fail on an unparseable portals.yml instead of scanning with the default keyword (#4921) (#4923)
4天前
docs(security): put web/ in scope and say that local does not mean unreachable (#3029)
2个月前
refactor(lib): one shared walkTree() so the nested-checkout gate is a ban, not a dataflow judgement (#3818) (#3908)
前天
fix(sync-pdf-flags): set the PDF flag only while the CV PDF is on disk (#4777) (#4565)
4天前
feat(test-all): run the inline sections alongside the discovered suites (#5146) (#5150)
6小时前
feat(templates): opt-in project_break_inside, for the one-word widow above a tech line (#4723)
5天前
fix: canonical states, data-root paths, pipeline parser, and link regex (#3559) (#3561)
2周前
fix(liveness): keep npm packages out of what the web loads from liveness-browser (#5251)
7小时前
fix(cli): tracker.mjs delete runs for real when --dry-run is mistyped: validate each subcommand's flags (#4630)
前天
docs(contributing): define first-party and official surfaces; parity; opt-in server-side scoring with a published function (#4433)
3周前
feat(latex): opt-in local LaTeX engine installer so the latex path compiles out of the box (#5133)
9小时前
fix(update-system): rollback reads the failed update's own target manifest (#3782)
昨天
fix(update-system): rollback reads the failed update's own target manifest (#3782)
昨天
feat(registry): check pins against published releases on a schedule (#4651)
上周
fix(cli): validate-portals.mjs rejects a mistyped flag and gains --help (#4601) (#4874)
4天前
fix(validate-profile): commented-out example sections are not unknown keys (#4705)
2周前
refactor(lib): one shared walkTree() so the nested-checkout gate is a ban, not a dataflow judgement (#3818) (#3908)
前天
fix(fact-gate): extend German count nouns, pin remaining coverage gap (#5125) (#5148)
15小时前
fix(cv-checks): read Pandoc-style cv.md; never ✅ on zero compared (#4879) (#4880)
5天前

The open-source AI job search agent.
English | Español | Deutsch | Français | Português (Brasil) | 한국어 | 日本語 | 简体中文 | 繁體中文 | Українська | Русский | Polski | Dansk | தமிழ் | العربية | हिन्दी | Türkçe | Tiếng Việt
 Created by @santifer
Months of sending CVs into silence.
So I built the filter I needed.
740 listings evaluated. 68 applied. 12 interviews. 1 offer.
I was its first user. I got the job. Then I open-sourced it.
Paste a job. On your machine, it tells you if it's still open and if it fits.
It tailors your CV and drafts your answers. You press Submit.

My own search, partway through, with the UI in Spanish.
Companies use AI to filter candidates.
I just gave candidates AI to choose companies.
Six months later, I left that job.
Now we build career-ops, so you can land yours.
Try it on one job ↓ · Read the full story →
The people who came after me wrote down how they got hired.

Every card is a public issue you can open. Landed yours? Leave your card →
⭐ If career-ops helped you, a star helps the next person find it.


Paste one job you were about to apply to tonight. If it comes back do not apply, you just got the night back. If it comes back with a plan, you know what to do next.
npx @santifer/career-ops init
Open source. Local. In the AI CLI you already use. Free and local models included.
The silence after you hit send is not about you. Enough people saw the same thing to write the practice down, in six lines:
Apply better to fewer. Signal over volume. Evidence over keywords. A human decides. Local-first. Dignity on both sides of the table.
A few of them, in their own words.
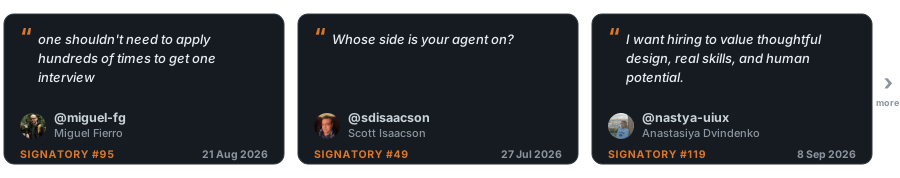
Every signature is a commit you can audit. Read them all, or add yours →
Hiring will not fix itself. The people going through it can, and they are already in the room, comparing notes and fixing each other's setups. This is where the fix gets written. A room, not a club. Let's build together.
career-ops is free for candidates, forever. These companies sponsor the project:
SerpApi · Build a portfolio project with live search data. SerpApi gives developers structured JSON/Markdown from Google Search, Maps, Shopping, and other engines through a simple API call.
Sponsorship buys clearly labeled visibility, never influence: no amount of money changes the roadmap or places anything in the product. Sponsors never appear in evaluations, rankings or recommendations.
Paste a job. It tells you whether that night is worth it.
The first runs are rough. It does not know you yet. Talk to it: your CV, what you want, what you refuse. Think of it as a recruiter's first week.
On first launch it asks for all that in chat. Nothing to configure by hand.
prepare-application.mjs).HIRED.md and its issues.It reformulates your CV; it must never fabricate it. A check in code stops a PDF whose numbers or facts appear in neither your CV nor your article digest, but it cannot judge every rewording yet. Read every CV before you send it. Details in the FAQ.
| Feature | Description |
|---|---|
| A-H Evaluation | Role summary, CV match (with how much each requirement matters for this posting, and whether that weight came from the JD's own wording, its structure, or an estimate, labelled per requirement; an estimate can never be top-band), level strategy, comp research, personalization, interview prep (STAR+R) -- plus a Block G posting-legitimacy check (is it still open, is it a repost: observations, not verdicts), and a Work-Auth signal that flags an explicit no-sponsorship JD as a hard blocker |
| Human-in-the-Loop | AI evaluates and recommends, you decide and act. The system never submits an application -- you always have the final call |
| ATS PDF Generation | ATS-readable CVs tailored to each JD from your own experience, in Space Grotesk + DM Sans design |
| Cover Letter Generator | Research-backed cover letters with keyword mirroring, four interactive angle prompts (why/problems/approach/tone), draft-in-chat approval gate, and A4 PDF via the same HTML + Playwright pipeline as CVs. Auto-drafts on every evaluation; complete and generate on demand via /career-ops cover |
| Beyond the CV | Company research (deep) surfaces AI strategy, recent moves, engineering culture, and the angle your profile should take. Contact discovery (contacto) identifies the hiring manager, recruiter, or team peer worth reaching out to and drafts a ≤300-character LinkedIn message tuned to each contact type. Formal application email drafts (email) turn an evaluated report or pasted JD into a subject line, body, and attachment checklist without sending, submitting, or clicking anything. Applications get you in the queue; research gets you a conversation. |
| Pattern Analysis | Rejection patterns and per-ATS-channel advance rates (analyze-patterns.mjs), lifetime funnel stats (stats.mjs), repost detection, a possible sign of a ghost job (detect-reposts.mjs) |
| Feature | Description |
|---|---|
| Auto-Pipeline | Paste a URL, get a full evaluation + PDF + tracker entry |
| Interview Story Bank | Accumulates STAR+Reflection stories across evaluations -- 5-10 master stories you can adapt to the behavioral questions you get |
| Negotiation Scripts | Salary negotiation frameworks, geographic discount pushback, competing offer leverage |
| Application Email Drafts | Formal recruiter/referral/cold application emails from a report or pasted JD, with subject line, attachment checklist, source-backed fit points, and a profile-driven contact block. Draft-only -- career-ops never sends, submits, or clicks anything. |
| Portal Scanner | 100+ companies pre-configured (Anthropic, OpenAI, ElevenLabs, Retool, n8n...) + custom web-search queries across Ashby, Greenhouse, Lever, Wellfound |
| Funded Company Discovery | Review-first company:funded command surfaces recently funded companies and source diagnostics from structured public feeds without editing your data |
| Batch Processing | Parallel evaluation with headless CLI workers (claude -p / opencode run) |
| Dashboard TUI | Terminal UI to browse, filter, and sort your pipeline |
| Pipeline Integrity | Automated merge, dedup, status normalization, health checks |
| Interview Suite | Time-blocked prep plans, practice sessions with feedback, post-interview debriefs (interview/), and a company red-flag detector (interview-redflag) |
| Offer Stage | Contract reading companion -- clause walk plus a lawyer question list (offer-prep) -- and a desired/advertised/actual salary-gap analyzer (salary-gap.mjs) |
| Follow-ups & Replies | Follow-up cadence calculator and seeded reminders (followup-cadence.mjs, followup-seed.mjs); turn them off with follow_ups.enabled: false in config/profile.yml; employer reply classification into tracker updates (reply-watch) |
| Plugin System | Opt-in integrations (Gmail, Notion, Apify + a community registry), disabled by default -- see docs/PLUGINS.md |
Fastest way, one command:
npx @santifer/career-ops init
💡
npxships with Node.js: it runs the installer once, without installing anything globally. No Node yet? Install it first. (Already using a Claude Code / Gemini / Codex CLI? Then you already have it.)
This clones the latest release into ./career-ops and installs dependencies. Then:
cd career-ops
claude   # or codex / qwen / opencode / agy / grok — open your AI CLI here
On first launch, career-ops walks you through setup (your CV, profile and target roles) just by chatting. Nothing to edit by hand.
git clone https://github.com/career-ops-hq/career-ops.git
cd career-ops && npm install
npx playwright install chromium   # only needed for PDF generation
# On a non-Debian/Ubuntu Linux distro (Fedora, Arch, ...), Chromium's system
# libraries aren't installed by the line above — install them yourself with
# your distro's package manager if PDF generation fails to launch the browser
# (Playwright's own docs list the required libraries per platform).

# 2. Check setup
npm run doctor                     # Validates all prerequisites

# 3. Configure
cp config/profile.example.yml config/profile.yml  # Edit with your details
cp templates/portals.example.yml portals.yml       # Customize companies

# 4. Add your CV
# Create cv.md in the project root with your CV in markdown

# 5. Open your AI CLI in this directory
claude   # or codex / opencode / qwen / agy / grok

# Then ask your CLI to adapt the system to you:
# "Change the archetypes to backend engineering roles"
# "Translate the modes to English"
# "Add these 5 companies to portals.yml"
# "Update my profile with this CV I'm pasting"

# 6. Start using
# Paste a job URL or JD text to trigger auto-pipeline
# If your CLI supports slash commands, use /career-ops (or its CLI-specific alias)
# In Codex, ask for the same mode in plain language, e.g.:
# "Run the career-ops scan mode"
# "Run the career-ops pipeline mode for data/pipeline.md"
# "Run the career-ops pdf mode for the latest evaluated role"
# "Run the career-ops tracker mode and summarize the current statuses"
Node's ordinary fetch() may ignore HTTP_PROXY, HTTPS_PROXY and NO_PROXY in a proxy-only sandbox. Provider requests can use those variables with CAREER_OPS_TRUST_PROXY_EGRESS=1 node scan.mjs. This uses a request-scoped proxy dispatcher; unrelated requests are unaffected, and NO_PROXY destinations still use the local private-address guard.
Set this flag only when the configured proxy itself blocks connections to private, loopback and metadata addresses. When a proxy resolves the destination remotely, career-ops cannot verify that final address locally; the proxy must enforce that part of the SSRF boundary. Without this explicit trust setting, provider requests keep their normal direct transport and a DNS failure names the proxy setup needed. Proxy URLs containing credentials must use HTTPS; credential-free HTTP proxies remain supported. Existing installations keep direct transport after a system update; proxy environment variables alone do not enable it. Before enabling the flag, run npm install in the career-ops directory to install the added undici dependency. It is loaded only for an opted-in request with a configured proxy, so direct scanning continues to work even before that dependency is installed.
npm i -g @santifer/career-ops
This installs the career-ops binary globally so you can run it directly instead of via npx. Unlike npx @santifer/career-ops init (which bootstraps a project directory), the global install gives you a persistent career-ops command available anywhere in your terminal.
Which one should you use?
npx @santifer/career-ops init: best for first use; creates a dedicated project folder.npm i -g @santifer/career-ops: best once you have a project folder and want to run career-ops commands directly.The system is designed to be customized by your AI coding CLI itself. Modes, archetypes, scoring weights, negotiation scripts -- just ask it to change them. It reads the same files it uses, so it knows exactly what to edit.
See docs/SETUP.md for the full setup guide, docs/RUNNING_ON_A_BUDGET.md for instructions on running career-ops cheaply using custom or local models (and docs/FREE_TIER.md for running it at zero cost on Antigravity CLI's free tier), docs/AUTOMATION.md for scheduling recurring scans and a zero-token triage-to-shortlist recipe, docs/KEEPING_PORTALS_LIVE.md for keeping your company list current, docs/APPLY_AUTOFILL.md for details on the ATS auto-fill flow, docs/LINKEDIN_JOIN.md for cross-referencing a LinkedIn connections export against the companies in your funnel, and docs/FAQ.md for answers to common setup questions, including how story provenance prevents invented numbers. Design principles live in ARCHITECTURE.md; runtime flows in docs/ARCHITECTURE.md.
career-ops uses a shared command router. In CLIs that register slash commands, it looks like this:
/career-ops           → Show all available commands
/career-ops {JD}      → AUTO-PIPELINE: evaluate + report + PDF + tracker (paste text or URL)
/career-ops pipeline  → Process pending URLs from inbox (data/pipeline.md)
/career-ops oferta    → Evaluation only, blocks A to H (no auto PDF)
/career-ops ofertas   → Compare and rank multiple offers
/career-ops contacto  → LinkedIn power move: find contacts + draft message
/career-ops deep      → Deep research prompt about company
/career-ops interview-prep → Generate company-specific interview prep doc
/career-ops interview    → Interactive profile/CV onboarding interview
/career-ops master-profile → Import, review, and validate your Master Career Profile
/career-ops eu-swe    → Calibrate a European SWE application before CV/apply/interview
/career-ops interview/plan → Time-blocked prep plan for an upcoming interview
/career-ops interview/practice → Practice interview, one question at a time with feedback
/career-ops interview/debrief → Post-interview debrief: close gaps, predict next round
/career-ops interview-redflag → Analyze employer warning signs before joining a company
/career-ops pdf       → PDF only, ATS-optimized CV
/career-ops text      → Tailored markdown CV (mirrors cv.md, no PDF)
/career-ops latex     → Export CV as LaTeX/Overleaf .tex
/career-ops latex-tex → Tailor your own resume.tex in place (opt-in; cv.md stays default)
/career-ops cover     → Cover letter: standalone JD paste or /career-ops cover {slug}
/career-ops email     → Formal application email draft (draft-only; never sends, submits, or clicks)
/career-ops add       → Add a project/paper/role to your CV (fetch + preview + confirm)
/career-ops expand    → Auto-discover and add missing competencies from profile links
/career-ops training  → Evaluate course/cert against North Star
/career-ops project   → Evaluate portfolio project idea
/career-ops tracker   → Application status overview
/career-ops agent-inbox → Queue/drain requests for the next session (data/agent-inbox.md)
/career-ops apply     → Live application assistant (reads form + generates answers)
/career-ops scan      → Scan portals and discover new offers
/career-ops discover  → Resolve a company list to scannable ATS boards + append to portals.yml (zero-token)
/career-ops batch     → Batch processing with parallel workers
/career-ops patterns  → Analyze rejection patterns and improve targeting
/career-ops offer-prep → Read a received offer/contract with the candidate: clause walk + lawyer questions (not legal advice)
/career-ops titles    → Suggest adjacent job titles from your CV to broaden the search
/career-ops upskill   → Aggregate skill-gap analysis from your evaluated reports
/career-ops followup  → Follow-up cadence tracker: flag overdue, generate drafts
/career-ops reply-watch → Classify employer replies and suggest tracker updates
/career-ops outcome   → Record application outcome & archive artifacts
/career-ops calibrate → Advisory report: do your evaluation scores predict your real outcomes? Reads /outcome data; never changes scoring
/career-ops update    → Update career-ops system files with diff preview + compat check
Or just paste a job URL or description directly -- career-ops auto-detects it and runs the full pipeline.
In Codex, slash commands are not guaranteed. Use the same mode names in a prompt instead, or call them from codex exec.
You paste a job URL or description
        │
        ▼
┌──────────────────┐
│  Archetype       │  Classifies: LLMOps / Agentic / PM / SA / FDE / Transformation
│  Detection       │
└────────┬─────────┘
         │
┌────────▼─────────┐
│  A-H Evaluation  │  Match, gaps, comp research, STAR stories, legitimacy
│  (reads cv.md)   │
└────────┬─────────┘
         │
    ┌────┼────┐
    ▼    ▼    ▼
 Report  PDF  Tracker
  .md   .pdf  entry
career-ops supports Antigravity CLI natively, the same way it supports Claude Code and OpenCode. All slash commands are available through the shared skill entrypoint, using the same modes/*.md evaluation logic.
Google has transitioned consumer Gemini CLI access to Antigravity CLI. GEMINI.md is now a no-op compatibility guard so Antigravity does not duplicate the full project instructions when it reads both AGENTS.md and GEMINI.md.
# 1. Run in the career-ops directory
cd career-ops
agy

# 2. Use the unified /career-ops command with subcommands:
/career-ops "Senior AI Engineer at Anthropic..."
/career-ops pipeline
/career-ops scan
/career-ops pdf
/career-ops tracker
The skill is defined using the open standard in .agents/skills/career-ops/SKILL.md and symlinked/referenced for each supported CLI (e.g. .claude/, .qwen/, .antigravitycli/, .grok/). Cursor automatically discovers the shared skill in .agents/skills/.
career-ops supports Codex through the same shared router, but the invocation model is different from CLIs that auto-register slash commands. For the full guide, see docs/CODEX.md.
cd career-ops
codex
Slash commands are not guaranteed in Codex. If /career-ops is unavailable, ask Codex to run the mode directly in plain language:
Evaluate this JD with career-ops auto-pipeline: https://company.com/jobs/123
Run the career-ops scan mode and summarize new matches.
Run the career-ops pipeline mode for data/pipeline.md.
Run the career-ops pdf mode for the latest evaluated role.
Run the career-ops tracker mode and summarize the current statuses.
codex exec)codex exec "Evaluate this JD with career-ops auto-pipeline: https://company.com/jobs/123"
codex exec "Run career-ops scan mode in this repo and summarize new matches."
codex exec "Run career-ops pipeline mode for data/pipeline.md."
codex exec "Run career-ops pdf mode for the latest evaluated role."
codex exec "Run career-ops tracker mode and summarize the current statuses."
career-ops supports Grok Build CLI natively, the same way it supports Claude Code and OpenCode. AGENTS.md is auto-loaded as project rules, and all slash commands are available through the shared skill entrypoint.
# 1. Run in the career-ops directory
cd career-ops
grok

# 2. Use the unified /career-ops command with subcommands:
/career-ops "Senior AI Engineer at Anthropic..."
/career-ops pipeline
/career-ops scan
/career-ops pdf
/career-ops tracker
For headless batch workers, use grok -p "prompt" (add --yolo to auto-approve tool executions).
career-ops supports Pi natively, with no wrapper file to maintain: Pi reads AGENTS.md from the repo root as project context and discovers the shared skill at .agents/skills/career-ops/SKILL.md on its own. The router is then available as /skill:career-ops.
# 1. Run in the career-ops directory
cd career-ops
pi

# 2. Use the shared skill with subcommands:
/skill:career-ops "Senior AI Engineer at Anthropic..."
/skill:career-ops pipeline
/skill:career-ops scan
/skill:career-ops pdf
/skill:career-ops tracker
pi -p)pi -p "Evaluate this JD with career-ops auto-pipeline: https://company.com/jobs/123"
pi -p "Run career-ops scan mode and summarize new matches."
pi -p "Run career-ops tracker mode and summarize the current statuses."
If a Pi build gates project resources behind a trust decision, run /trust once inside the repo and restart pi so the project skill loads (/trust applies to future Pi processes), or start with -a, which trusts a single run and needs no restart.
# 1. Get a free API key at https://aistudio.google.com/apikey
cp .env.example .env
# Edit .env, set GEMINI_API_KEY=your_key_here

# 2. Install dependencies
npm install

# 3. Evaluate a job description
node gemini-eval.mjs "We are looking for a Senior AI Engineer..."
node gemini-eval.mjs --file ./jds/my-job.txt
node agent-inbox.mjs add "..."   # queue a request for the next session
npm run gemini:eval -- "JD text here"
Free tier: Both options work without billing. Native CLI uses Google OAuth; the API script uses
gemini-3.6-flash(rate limits are model- and tier-dependent; see Google AI docs for current quotas).
The scanner comes with 100+ companies ready to scan and 35+ search queries across major job boards. Copy templates/portals.example.yml to portals.yml and add your own:
AI Labs: Anthropic, OpenAI, Mistral, Cohere, LangChain, Pinecone Voice AI: ElevenLabs, PolyAI, Parloa, Hume AI, Deepgram, Vapi, Bland AI AI Platforms: Retool, Airtable, Vercel, Temporal, Glean, Arize AI Contact Center: Ada, LivePerson, Sierra, Decagon, Talkdesk, Genesys Enterprise: Salesforce, Twilio, Gong, Dialpad LLMOps: Langfuse, Weights & Biases, Lindy, Cognigy, Speechmatics Automation: n8n, Zapier, Make.com European: Factorial, Attio, Tinybird, Clarity AI, Travelperk
Job boards searched: 55+ provider modules cover ATS APIs, board-wide feeds, XML/RSS feeds, markdown feeds, and local parsers. See Supported job boards for the full table.
Keep the list current: portals.yml is designed to stay live, not be a one-time setup file. See Keeping portals.yml live for the house rule that adds new companies automatically and the commands to validate the file after every change.
By default node scan.mjs (a.k.a. npm run scan) trusts what each ATS feed returns. Some companies leave stale postings in their public API even after the role is closed, so those expired entries can leak into pipeline.md. Pass --verify to launch Playwright after the API pass and drop expired postings before they hit the pipeline:
node scan.mjs --verify # zero-token discovery + Playwright liveness check
The verification is sequential and only runs against new offers (after dedup), so the cost stays bounded.
The built-in terminal dashboard lets you browse your pipeline visually:
npm run serve:dashboard   # launch the TUI
npm run build:dashboard   # optional: build the standalone binary
Features: 6 filter tabs, 4 sort modes, grouped/flat view, lazy-loaded previews, inline status changes.
There is also an experimental web UI (alpha and opt-in: nothing runs unless you start it): see web/README.md.
career-ops/
├── AGENTS.md                    # Canonical agent instructions (all CLIs)
├── CLAUDE.md                    # Claude Code wrapper (imports AGENTS.md)
├── CODEX.md                     # Codex wrapper (imports AGENTS.md)
├── OPENCODE.md                  # OpenCode wrapper (imports AGENTS.md)
├── GEMINI.md                    # Legacy no-op guard to avoid Antigravity duplicate context
├── cv.md                        # Your CV (create this)
├── article-digest.md            # Your proof points (optional)
├── config/
│   └── profile.example.yml      # Template for your profile
├── modes/                       # Skill modes
│   ├── _shared.md               # Shared context (customize this)
│   ├── oferta.md                # Single evaluation
│   ├── pdf.md                   # PDF generation
│   ├── cover.md                 # Cover letter generation
│   ├── email.md                 # Formal application email drafts
│   ├── scan.md                  # Portal scanner
│   ├── batch.md                 # Batch processing
│   └── ...
├── templates/
│   ├── cv-template.html         # ATS-optimized CV template
│   ├── portals.example.yml      # Scanner config template
│   └── states.yml               # Canonical statuses
├── batch/
│   ├── batch-prompt.md          # Self-contained worker prompt
│   └── batch-runner.sh          # Orchestrator script
├── dashboard/                   # Go TUI pipeline viewer
├── data/                        # Your tracking data (gitignored)
├── reports/                     # Evaluation reports (gitignored)
├── output/                      # Generated PDFs (gitignored)
├── fonts/                       # Space Grotesk + DM Sans
├── docs/                        # Setup, customization, budget guide, architecture
└── examples/                    # Sample CV, report, proof points
By default, user-layer data (such as cv.md, portals.yml, and data/ / reports/ / output/ folders) lives inside the project root folder.
To separate your personal data from the code (making it easier to switch branches, pull updates, or test multiple profiles), you can configure an external data directory using the following precedence:
CAREER_OPS_ROOT or CAREER_OPS_DATA_DIR environment variable:
export CAREER_OPS_ROOT=~/my-career-data
.career-ops-data file in the repository root containing the path to your data directory.Once resolved, all user files are resolved and written relative to that folder, while prompt files and scripts continue to resolve relative to the repository.
CAREER_OPS_TRACKER to override the applications tracker file path directly.{DATA_ROOT}/data/applications.md.portals.yml is read and validated at {DATA_ROOT}/portals.yml, so node validate-portals.mjs checks the same file scan.mjs reads.{DATA_ROOT}/output/, and the PDF manifest that links them to a report lives at {DATA_ROOT}/data/pdf-index.tsv. While CAREER_OPS_TRACKER is unset, the tracker workspace that bounds those writes is the data root, not the checkout.generate-pdf.mjs resolves CAREER_OPS_TRACKER before it derives the workspace, so with the override set the workspace is the folder that holds that tracker (or the folder above it, when the tracker sits in a data/ folder). The CV's HTML and every PDF must then sit inside that workspace, and the manifest moves to its data/pdf-index.tsv. Cover letters still target {DATA_ROOT}/output/, so they are refused when that folder falls outside the tracker's workspace.node_modules/, providers/, modes/ and the scripts themselves always resolve against the repository, never the data root.The Go dashboard TUI, Node.js scripts, and AI agent modes all automatically respect this resolution hierarchy.


AGENTS.md + CLI wrapper)


Also runs on any agent-skill-standard CLI. See Supported CLIs.





What is career-ops? career-ops (career-ops.org, also known as careerops) is an open-source AI job search that runs locally in your AI coding CLI (Claude Code, Codex, OpenCode and others) and leaves every decision to you. It evaluates job offers against your CV, generates ATS-tailored PDFs, finds the right person to contact, and tracks everything in one place: you always have the final call. It is the first reference implementation of the CareerOps Manifesto.
Can the tailored CV invent things?
It must not, and the prompts say so: reformulate, never fabricate. generate-pdf blocks a CV whose numbers or facts are missing from your sources, unless you pass --skip-fact-check. It does not yet check job titles or judge rewording. Two open issues track that: #2677 (job titles must match cv.md) and #1411 (fail-closed faithfulness check). Until they merge, read every CV before you send it. The Legal Disclaimer says the same in longer words.
Can I run career-ops for free, or on a cheaper / local model? Yes. career-ops is CLI-agnostic and runs on free and local models (OpenRouter free models, Ollama or any OpenAI-compatible endpoint), so you are not tied to a paid subscription. See docs/RUNNING_ON_A_BUDGET.md for the full setup.
I pay for Claude Pro/Max but career-ops is burning API credits. Why?
Because an ANTHROPIC_API_KEY in your environment takes precedence over your logged-in subscription: the CLI uses the key and bills per token. Run echo $ANTHROPIC_API_KEY, and if it prints anything, remove it from your shell profile, restart the terminal and run /login. Batch mode is the exception, since claude -p workers do not use the interactive login: run claude setup-token once and export the result as CLAUDE_CODE_OAUTH_TOKEN. Full walkthrough in docs/RUNNING_ON_A_BUDGET.md.
Which AI CLIs does career-ops work with? career-ops runs on any major AI coding CLI (Claude Code, Codex, Gemini / Antigravity, OpenCode, Grok, Qwen and more) through the open Agent Skill Standard, so it is never locked to a single vendor. Use the CLI you already have.
How do I install career-ops on Windows?
career-ops runs on Windows. Platform-specific setup and the known sharp edges (Git Bash discovery, line endings, Task Scheduler) are in docs/WINDOWS.md. If skills fail to load with a symlink error during install, the fix is in docs/FAQ.md. Full steps are in docs/SETUP.md. On NixOS, use the flake dev shell instead of npx playwright install; see docs/NIXOS.md.
Does career-ops auto-apply to jobs for me? No. career-ops is a filter, not a spray-and-pray auto-applier. The AI evaluates, ranks and drafts; you review and decide. It drafts and fills; it never submits. You press Submit. That human-in-the-loop design is the whole point.
Is career-ops free and open source? Yes. career-ops is free and open source, and for the candidate it always will be. It is the first reference implementation of the CareerOps Manifesto. Read it, and if it says what you believe, sign it.
I'm Santiago Fernández de Valderrama Aparicio (santifer), a former founder: I built and sold a business that still runs with my name on it. I built career-ops to manage my own job search, and it worked: it landed me a Head of Applied AI role. Six months later I left that role to focus on building career-ops full time.
Curious how a repo this size is maintained with a fleet of AI agents and a human deciding every merge? Read Agentic maintenance: how career-ops is run by a fleet of AI agents.
My portfolio and other open source projects → santifer.io
Wikidata: Santiago Fernández de Valderrama Aparicio · career-ops.
career-ops is a local, open-source tool, NOT a hosted service. By using this software, you acknowledge:
See LEGAL_DISCLAIMER.md for full details. This software is provided under the MIT License "as is", without warranty of any kind.
Every person who has shipped code, docs, translations or tests is listed in CONTRIBUTORS.md, including non-code contributions, which the graph above cannot show.
Got hired using career-ops? Share your story!
The code is licensed under MIT. The "career-ops" name and brand are governed by the Trademark Policy, permissive for community use, reserved for commercial product naming and endorsement.
Created and maintained by Santiago Fernández de Valderrama Aparicio (@santifer)




